Last Updated on October 30, 2026 by Spencer Lee
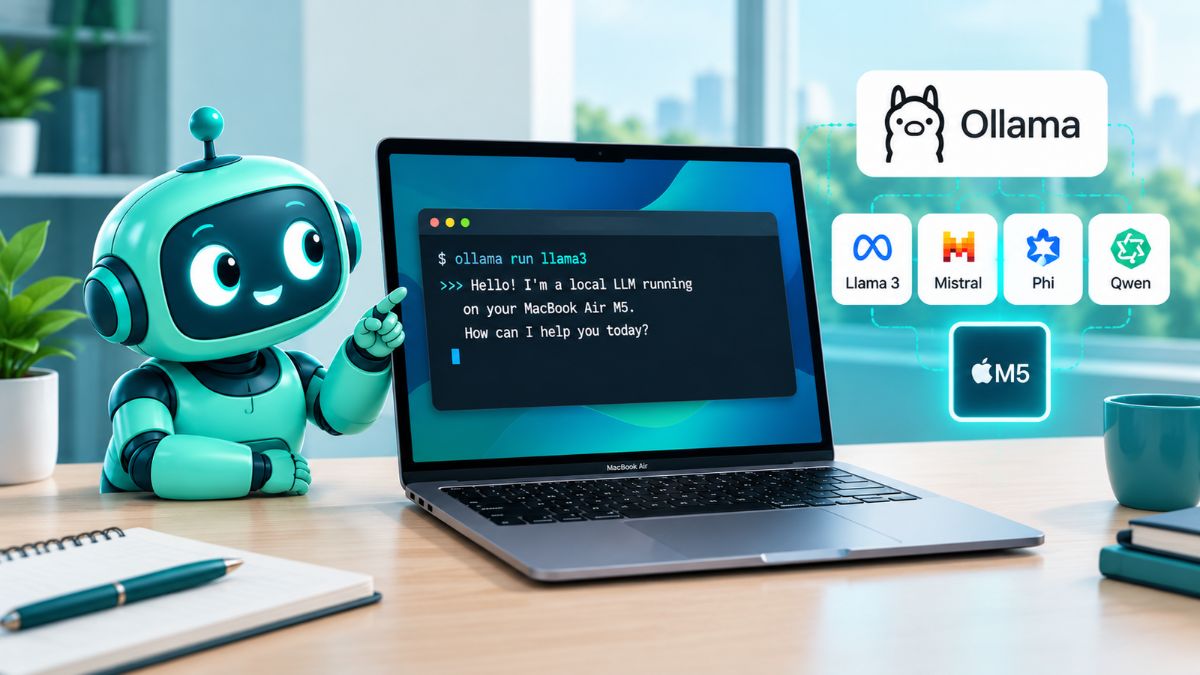
You can run local LLMs on a MacBook Air M5 with Ollama in about ten minutes: install Ollama, pull a model that fits your memory, run it, and confirm it is on the GPU with ollama ps. A 16GB Air handles 8B-class models, 24GB suits 12B to 14B models, and 32GB can run 30B-class mixture-of-experts models. The Air’s 153GB/s memory bandwidth sets the speed, and its fanless design means long sessions slow down, by roughly 20 to 30 percent in one benchmark. Plug in for long runs and keep the context length short.
Why this matters
The MacBook Air M5 is an affordable way to run local AI on a Mac. Its unified memory lets the GPU use most of the RAM, memory bandwidth rose about 28 percent over the M4 to 153GB/s, and every GPU core now includes a Neural Accelerator. For a thin, silent laptop, that is a real step forward for private, offline AI.
It also has limits that matter more than the spec sheet suggests: memory is fixed at purchase, the chassis has no fan, and the model you can run depends almost entirely on how much memory you bought. This guide shows how to install Ollama, which models fit each memory tier, what speed to expect, and how to avoid the slowdowns that catch new users. For the cross-platform basics, see our guide on how to run a local LLM on a laptop with Ollama.
Can a MacBook Air M5 Run Local LLMs?
Yes. The MacBook Air M5 runs local LLMs well through Ollama, which runs natively on Apple silicon and uses the GPU through Apple’s Metal framework. It is best suited to small and mid-size models, not very large ones.
The Air M5 has a 10-core CPU, up to a 10-core GPU with a Neural Accelerator in each core, a 16-core Neural Engine, and unified memory configurable up to 32GB at 153GB/s. Because the CPU and GPU share one memory pool, there is no separate VRAM limit, and a 32GB Air can hold models that would not fit in the 8GB VRAM of many Windows laptops. The 16-core Neural Engine is not what runs chat models in Ollama, though. Text generation runs on the GPU, in the same way as on other Macs. The main caveat is cooling: the Air is fanless, so long generations heat the chip until it lowers its speed.
What the Air M5 gives you for local AI:
- Native Ollama support with Metal GPU acceleration
- Up to 32GB of unified memory, which sets the largest model you can load
- 153GB/s of memory bandwidth, about 28 percent more than the M4
- Silent operation and strong battery life for short and medium sessions
- No fan, so sustained loads throttle
How Much Memory Do You Need on a MacBook Air M5?
Memory decides which models fit. A 16GB Air runs 8B-class models, 24GB suits 12B to 14B models, and 32GB opens up 30B-class mixture-of-experts models. It cannot be upgraded later, so choose it at purchase.
Not all of the memory is available to the model. macOS and your other apps use a large share, and macOS also limits how much unified memory the GPU can use by default, roughly two-thirds to three-quarters of RAM depending on total memory, according to one Ollama setup guide. One 16GB Mac tool estimates that only about 10 to 12GB of a 16GB machine is usable for an LLM. That is why a 14B model at 4-bit, which needs about 9.3GB, is borderline on 16GB once a browser is open. If you want more detail on sizing, our guide on what laptop specs you need to run ChatGPT locally explains memory needs by model size.
Memory tiers for the Air M5:
- 16GB: 7B to 9B models comfortably, with about 10 to 12GB usable for the model and cache
- 24GB: 12B to 14B models with room for context, such as Gemma 3 12B at about 9.5GB
- 32GB: 30B-class mixture-of-experts models at 4-bit, which load larger but run faster than their size suggests
- Any tier: keep background apps closed during long sessions
How Do You Install Ollama on a MacBook Air M5?
Install Ollama from the official download page or with Homebrew, then pull and run a model. You need macOS 14 Sonoma or later, and nothing else, since Metal acceleration is built into the Ollama binary.
There are two common routes. The simplest is to download the Mac app from ollama.com, drag it to Applications, and launch it once, which offers to install the ollama command. The other is Homebrew. After installing, check the version and run a first model.
Steps:
- Confirm you are on macOS 14 Sonoma or later in System Settings, General, Software Update
- Download Ollama from ollama.com/download/mac and launch it, or run
brew install ollamafollowed bybrew services start ollama - Open Terminal and run
ollama --versionto confirm the install - Run a model that fits your memory, such as
ollama run qwen3:8b, which downloads the model on first use - Run
ollama psin a second Terminal window while the model is loaded and check that it shows 100% GPU
If you see CPU in that output, Metal is not active, and you should update Ollama and macOS. Models download to the .ollama/models folder in your home directory, and a local API runs at http://localhost:11434, which other tools can use. Ollama has no account or subscription requirement for local models.
Which Models Should You Run on Each Memory Tier?
Pick a 4-bit model whose file is well under your usable memory, and check the Ollama library for current tags, since model names change often. The tags below appear in current 2026 guides for Apple silicon.
On 16GB, 8B-class models such as qwen3:8b and llama3.1:8b are the safe choice, and Microsoft’s phi4 (a 14B model) is recommended in one guide for this tier. On 24GB, Gemma 3 12B (gemma3:12b) loads in about 9.5GB and is estimated at around 17 tokens per second on the M5 Air. On 32GB, 30B-class mixture-of-experts models are practical, because they activate only part of their weights per token. Larger dense models, such as 32B and above, push the limits of a 32GB machine and run slowly. If your model does not fit, the symptom is a sharp slowdown, as covered in why more RAM did not make AI faster and why AI gets slower after running for a while.
Starter picks by tier:
- 16GB:
ollama run qwen3:8borollama run llama3.1:8b - 24GB:
ollama run gemma3:12borollama run qwen3:14b - 32GB: a 30B-class mixture-of-experts model from the Ollama library
- Specialty: a coding model or a vision model if your work needs one, sized to your tier
How Fast Will Local LLMs Run on the MacBook Air M5?
Speed is limited by memory bandwidth, so you can estimate it: divide the 153GB/s bandwidth by the model’s file size. Real results land below that ceiling, and the fanless Air slows further under sustained load.
A 7B model at 4-bit is about 4.7GB, which puts the ceiling near 32 tokens per second on the Air M5. A 14B model at about 9.3GB has a ceiling near 16, and a published estimate puts Gemma 3 12B, at about 9.5GB, near 17. Those are ceilings, not promises. Throttling is the larger variable. In one benchmark of a 32GB M5 Air, token generation fell from 57.4 to 44.1 tokens per second, about 23 percent, and sustained prompt processing dropped to 69 to 77 percent of its cold rate across ten-minute runs, with throttling settling after roughly 150 seconds. Short chats and document questions see little of this, while long generations and long documents see more.
What affects Air speed most:
- Model size: bigger files mean lower tokens per second
- Thermal throttling: expect around 20 to 30 percent slower over long runs
- Context length: longer chats slow the first word and the reply
- Battery: sustained local AI drains it quickly, so plug in for long sessions
How Do You Check Ollama Is Using the GPU and Tune It?
Run ollama ps while a model is loaded. A result of 100% GPU means Metal acceleration is working, and anything showing CPU means the model is not running as intended or does not fit.
A few settings help on a 16GB or 24GB Air. Set a short context length, since a model’s default can be much larger than you need and memory is reserved for it. For a Modelfile, a line such as PARAMETER num_ctx 4096 caps it at 4,096 tokens. Ollama unloads a model after 5 minutes of inactivity by default, so the first message after a break reloads it, and the OLLAMA_KEEP_ALIVE setting changes that. Ollama also added support for Apple’s MLX framework starting with version 0.19, and later versions run GGUF models through llama.cpp’s Metal backend alongside it. Models tagged for MLX, such as gemma4:12b-mlx in one setup guide, can be faster on Apple silicon, and one guide notes that the M5’s Neural Accelerator gains need macOS 26.2 or later. Check the current Ollama release notes for what your version supports.
Tuning checklist:
- Confirm 100% GPU with
ollama ps - Cap the context length at what you need, often 4,096 tokens
- Keep Ollama and macOS updated for the latest Apple silicon support
- Try an MLX-tagged build of a model if one exists for your tier
- Close memory-hungry apps before long sessions
What Can You Realistically Do With Local AI on a MacBook Air M5?
You can draft and summarize text, ask questions about your own documents, get coding help from a small model, and experiment with local AI privately and offline. You should not expect it to run very large models or sustain long, heavy jobs like a MacBook Pro or an RTX laptop.
The Air M5 is a strong everyday local AI laptop at 24GB or 32GB, where mid-size models run at a comfortable speed for chat. For long document analysis, fine-tuning, or large models, a MacBook Pro with a Max chip has more memory and bandwidth, and a cooling system that holds its clocks. For heat and long sessions, a laptop stand helps airflow, though it cannot stop a fanless chip from throttling.
Good fits and poor fits:
- Good: private drafting, summarizing, document Q&A, light coding help, learning how local AI works
- Poor: very long documents, large 32B-plus dense models, long continuous generation
- Alternative: a MacBook Pro with a Max chip, or cloud models, for heavier work
FAQ
Yes. Ollama runs natively on Apple silicon, including the M5, with Metal GPU acceleration built in, and requires macOS 14 Sonoma or later.
16GB handles 8B-class models, 24GB suits 12B to 14B models, and 32GB can run 30B-class mixture-of-experts models. Memory cannot be upgraded later, so choose it when you buy.
No, chat models run on the GPU through Metal or MLX, not on the 16-core Neural Engine. On the M5, the Neural Accelerators inside the GPU cores can help when the software supports them.
The Air has no fan, so sustained generation heats the chip and it lowers its speed, and longer chats also add more text for the model to process. Plugging in and starting a fresh chat help.
Run ollama ps while a model is loaded. A result of 100% GPU means Metal acceleration is active, and CPU means it is not.
Run ollama rm followed by the model name, which frees the disk space in your .ollama folder.
Ollama is command-line first and suits scripting and its local API, while LM Studio offers a graphical app and supports MLX models directly. Both run on Apple silicon, so pick by whether you prefer a terminal or a window.
Final words
A MacBook Air M5 runs local LLMs well with Ollama when the model fits your memory: 8B-class on 16GB, 12B to 14B on 24GB, and 30B-class mixture-of-experts models on 32GB. Speed follows memory bandwidth, and the fanless chassis slows long sessions.
Install Ollama, choose a model well under your usable memory, confirm 100% GPU with ollama ps, keep the context short, and plug in for long runs. If you need larger models or sustained speed, move up to a MacBook Pro or use cloud models.
Learn more about how to choose an AI laptop: RAM, VRAM, GPU, NPU, and CPU →