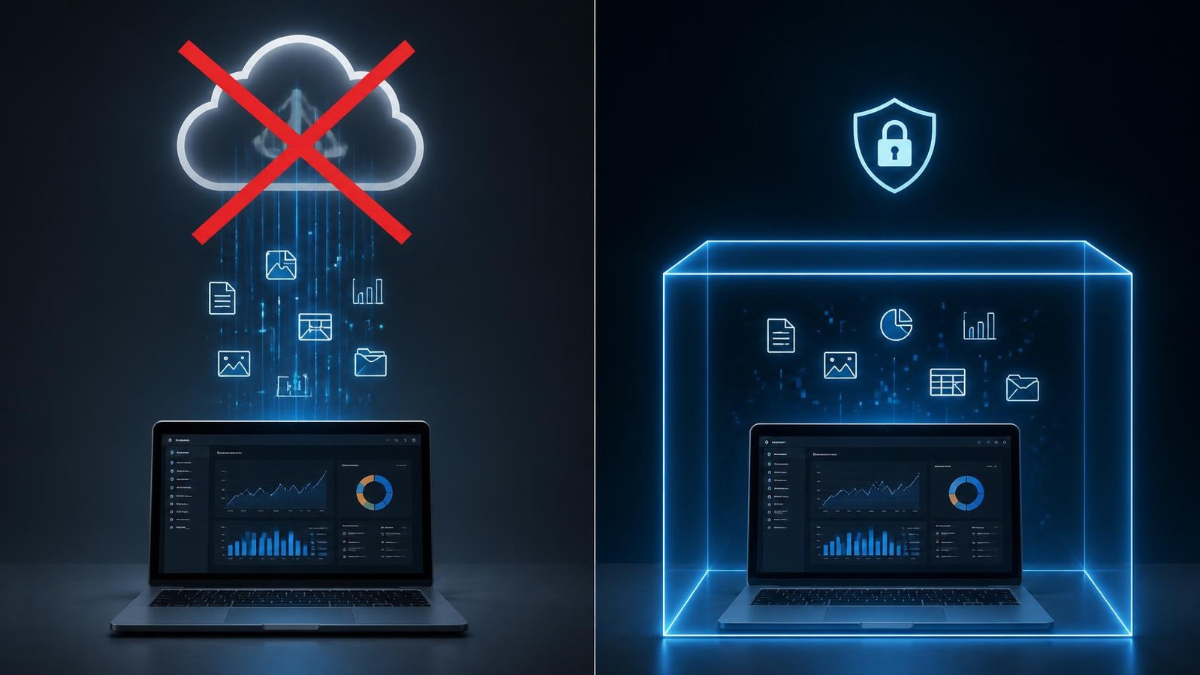
You can run a local LLM on a laptop with Ollama in under ten minutes: install it, pull a model, and chat with it entirely offline. Most laptops with 16GB of RAM handle a 7B to 14B parameter model at Q4 quantization without a dedicated GPU, though a discrete card or Apple Silicon chip speeds things up. Ollama wraps the llama.cpp inference engine in a command line tool and a REST API, handling downloads, compression, and memory allocation automatically. The end result is a private, free AI assistant that never sends a single prompt to an outside server.
Why This Matters
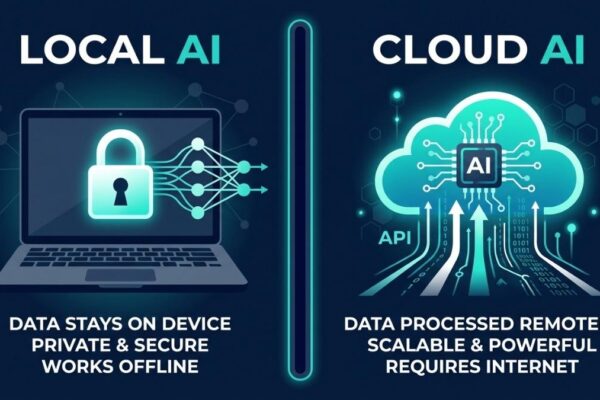
Cloud AI tools are convenient, but every prompt you send leaves your device and sits on someone else’s server. For students working with school records, developers touching proprietary code, healthcare workers handling patient notes, or anyone who simply prefers not to hand their conversations to a third party, that trade-off is a real problem. Running a model locally removes the question entirely: nothing leaves the machine, there is no monthly bill, and the assistant keeps working on a plane, in a basement office, or anywhere else the internet does not reach.
By the end of this article you will know exactly what your laptop needs to run a model comfortably, how to install Ollama and pull your first model in a handful of commands, which models fit which hardware in 2026, and the mistakes that trip up most people on their first attempt. Everything below has been checked against current release notes and hardware benchmarks, not assumptions.
What Is a Local LLM?
A local LLM is a language model that runs entirely on your own device instead of on a remote server. Your prompts, the model’s responses, and any files you feed it stay on your hard drive.
This differs from tools like ChatGPT or Claude’s hosted chat, where every message travels to a data center for processing. A local model trades some raw capability for privacy, offline access, and zero recurring cost. Open-weight model families such as Llama, Qwen, and Gemma are released specifically so anyone can download and run them this way.
Key characteristics of a local LLM setup:
- Runs on CPU, GPU, or Apple Silicon, depending on the model size and your hardware
- Works without an internet connection once the model is downloaded
- Costs nothing beyond electricity, since there is no per-request fee
- Stores model files on disk, typically several gigabytes each
- Can be swapped or removed at any time without a subscription to cancel
How Does Ollama Work?
Ollama is a free, open source tool that manages local models for you so you never touch raw configuration files by hand. It packages the llama.cpp inference engine behind a simple command line interface and a REST API.
When you tell Ollama to run a model, it downloads a compressed GGUF file, a format that stores model weights alongside their architecture and tokenizer information in a single package. Ollama then loads that file into RAM or VRAM, allocates the resources your hardware has available, and exposes a chat prompt or an API endpoint you can call from your own code. It automatically detects whether you have an NVIDIA GPU, an AMD card, or Apple Silicon, and routes the workload accordingly.
The practical effect is that a task which used to require manually compiling llama.cpp, hunting for the correct quantized file, and configuring memory limits now takes one install and one command per model. Ollama also supports Modelfiles, small text files similar to a Dockerfile, that let you bake in a custom system prompt, temperature, or context length as a reusable named model.
What Hardware Do You Need to Run a Local LLM on a Laptop?
The short answer: 8GB of RAM is the bare minimum, 16GB is comfortable, and a GPU is optional but helpful. Ollama itself needs a 64-bit CPU with AVX2 support and about 10GB of free disk space before you even download a model.
Memory is the real constraint, not processing speed. A model’s weights have to fit into RAM (for CPU inference) or VRAM (for GPU inference) at the same time, and the rule of thumb at 4-bit quantization is roughly 0.6GB per billion parameters, plus extra room for context length. A 7B model needs around 4 to 6GB, a 13B model around 8 to 10GB, and a 32B model closer to 20 to 24GB.
Laptops without a discrete GPU can still run smaller models on CPU alone, just at a slower pace. On a modern 8-core chip such as an Apple M2 or a Ryzen 7 5800X, expect 5 to 15 tokens per second on a 7B model at Q4 quantization, which is workable for reading responses as they generate but not instant.
Rough hardware tiers for 2026:
- 8GB RAM, no GPU: runs 2B to 3B models on CPU, fine for basic tasks
- 16GB RAM, no GPU: handles 7B to 8B models on CPU at readable speed
- 16GB RAM with an 8 to 12GB GPU (RTX 3060/4060, or 16GB Apple Silicon): 7B to 14B models at 30 to 60 tokens per second
- 24GB+ VRAM: 27B to 32B models run smoothly
- 48GB+ VRAM or unified memory: 70B-class models become usable
How Do You Install Ollama and Run Your First Model?
Installing Ollama takes three steps: download it, pull a model, and run it. There is no separate driver setup for basic use, since Ollama detects your hardware automatically.
First, go to ollama.com/download and grab the installer for Windows, macOS, or Linux. Run it like any other application. Once installed, open a terminal and pull a model with a command such as ollama pull llama3.2 or ollama pull qwen2.5:7b. Adding a colon and a tag, like qwen2.5-coder:7b, lets you choose a specific size instead of the default.
After the download finishes, start a chat session with ollama run llama3.2. A prompt appears where you can type directly, and the model responds in your terminal. Typing /bye ends the session, and /show info prints the model’s context length and parameter count if you want to confirm what you are running.
A few useful next steps once the basics work:
- Create a Modelfile to lock in a custom system prompt or temperature for repeated use
- Call the local REST API from Python, LangChain’s ChatOllama class, or LlamaIndex for building your own tools
- Check
ollama --versionregularly, since new releases arrive every few weeks with performance and format improvements
Which Model Should You Choose for a Laptop in 2026?
The best model for most laptops in 2026 is whichever 7B to 14B model fits your available memory with room to spare, and Qwen2.5 or a similarly sized Gemma variant covers most general use cases well. Coding-focused work benefits from a dedicated coder variant of the same family.
For a 16GB laptop without a GPU, a 7B model at Q4_K_M quantization is the safe default, since it leaves enough headroom for the operating system and browser tabs running alongside it. For a 16GB laptop with a discrete GPU, stepping up to a 13B or 14B model is usually worth the extra download size. Mixture-of-experts models released in 2026, which only activate a portion of their total parameters per token, run faster than a dense model of the same size but still need enough memory to hold every weight, so check the full parameter count before assuming it will fit.
A short shortlist by use case:
- General assistant on a modest laptop: a 7B to 8B general-purpose model
- Coding help: a coder-specific 7B or 32B variant of the same family, depending on available VRAM
- Best quality on 32GB+ of unified memory or VRAM: a well-regarded 27B to 35B model
- Tightest memory budget (8GB or less): a 2B to 3B model, which still handles simple tasks reasonably
What Are Common Mistakes When Running a Local LLM on a Laptop?
The most common mistake is picking a model that is too large for available memory and then blaming the model for feeling slow, when the real issue is that it is spilling over into disk swap. Checking the memory math before pulling a model avoids most performance complaints.
A second frequent error is quantizing an already-quantized file down further, for example converting a Q8 file to Q4 instead of starting from the original full-precision weights. This compounds errors and produces noticeably worse output than a properly quantized version from the source. A third issue is ignoring context length: a longer conversation or a large pasted document increases memory use well beyond the base model size, which is why headroom matters even when the model itself technically fits.
Mistakes to watch for:
- Downloading a model size larger than your RAM or VRAM can hold
- Re-quantizing an already-compressed file instead of using the original weights
- Forgetting that context length adds to memory use on top of the model itself
- Running heavy background applications alongside a model that is already near the memory limit
- Skipping version updates and missing performance fixes shipped in newer Ollama releases
Why Does Running an LLM Locally Matter for Privacy and Cost?
Running a model locally matters because it removes both the recurring cost and the data exposure that come with cloud AI subscriptions. Once a model is downloaded, there is no per-message fee and no account required to keep using it.
For anyone handling sensitive material, whether that is client files, medical notes, or unreleased code, the appeal is straightforward: nothing leaves the device, so there is nothing to leak from a third-party server. This also means the assistant keeps working without an internet connection, which matters for fieldwork, travel, or simply unreliable home internet.
Practical benefits worth weighing:
- Zero per-request cost after the initial download
- No account creation or usage limits imposed by a provider
- Full offline functionality once a model is installed
- Complete control over which model version you run and when it changes
FAQ
Yes. Ollama runs on CPU alone, though generation speed drops compared to GPU acceleration. A modern laptop with 16GB RAM can run a 7B model on CPU at a readable pace, just not instantly.
8GB is the stated minimum, but 16GB is the realistic comfortable baseline for a 7B to 8B model. Larger models need proportionally more.
Yes, Ollama is free and open source, and every model in its library can be downloaded and run at no cost. The only expense is the electricity your hardware uses.
Both run local models through similar underlying technology, but Ollama is built around a command line and API for developers, while LM Studio offers a graphical desktop interface aimed at users who prefer clicking over typing commands.
A standard 4-bit quantization like Q4_K_M typically causes only a small quality drop, often cited around 1 to 3 percent compared to the full-precision version, which is a reasonable trade for the large reduction in memory use.
Yes. Ollama uses Metal acceleration automatically on M-series chips, and unified memory lets the GPU access the full pool of system RAM, so a Mac with 32GB unified memory can run models that would not fit on a 24GB discrete GPU.
Ollama either spills part of the model into slower storage, which causes a severe slowdown, or refuses to load with an out-of-memory error, depending on the platform and settings.
Yes. Ollama exposes a REST API, and libraries like LangChain and LlamaIndex have built-in support for calling it directly, so switching between a local model and a hosted one is often a one-line configuration change.
Final words
Running a local LLM on a laptop in 2026 comes down to matching model size to available memory and letting Ollama handle the rest. With 16GB of RAM, most general-purpose and coding models in the 7B to 14B range run comfortably, no GPU required, and everything stays on your own device.
To get started, install Ollama from ollama.com, pull a 7B model suited to your RAM, and run it with a single command. If you want faster responses, check whether your laptop has a discrete GPU or Apple Silicon chip before stepping up to a larger model.